Running Inference & Profiling
Running any model on mobile and edge devices with specialized hardware may differ from running it on its reference environment. As you approach your target mobile or edge device, important questions arise:
Will the accuracy be similar even with float16 or int8 computations?
What is the inference latency across the target hardware?
Does the model fit within a certain memory budget?
Is my model able to leverage neural processing units?
Inference jobs using Qualcomm® AI Hub Workbench will help you answer all these questions.
Accuracy Questions
While your PyTorch implementation runs inference at float32 precision, the target hardware may run computations using float16 or even int8. This may lead to numerical discrepancies, as well as the possibility of underflows and overflows. Whether or not this has a detrimental effect on your results depends on your model and your data distribution.
Inference jobs provide you with a way to upload input data, run inference on real hardware, and download the output results. By comparing these results directly to your reference implementation, you can determine whether or not the optimized model works as expected.
Latency Questions
Inference jobs also support profiling to give you answers to latency, memory usage, and processing unit questions by running your model on real hardware and reporting fine-grained performance, memory usage, and processing units utilized. Profiling is enabled by default in inference jobs. When profiling is enabled the inference job results will include the compute unit used for each layer in your model, the runtime of each layer, and additional optracing and HTP runtime metrics.
submit_inference_job
Use submit_inference_job() to answer these questions. To get
stable state latency, inference will be run for 100 iterations. If profiling is enabled,
an additional iteration is run to gather per-layer metrics. The number of iterations
can be modified with the --max_profiler_iterations option (see Inference Options).
Inference is supported for models in the following formats:
QNN DLC, QNN context binary, ONNX, or TensorFlow Lite.
Models in source formats such as PyTorch (pt/pt2) and AIMET ONNX should be
compiled with submit_compile_job().
Inference jobs support the --qairt_version to select a specific Qualcomm® AI Runtime version.
If not specified, a version is selected according to Version Selection.
In the following examples, the profile argument is often passed as an explicit value to show different usages.
Running inference on a previously compiled model
Qualcomm® AI Hub Workbench supports running inference on a previously compiled model.
In this example, we optimize and run inference on a model that is previously compiled
using a submit_compile_job(). Note how we were able to use the
compiled model from compile_job using
get_target_model(). In this example, profiling is enabled.
import qai_hub as hub

client = hub.Client()

# Run inference with profiling on the previously compiled model
job = client.submit_inference_job(
    model=compile_job.get_target_model(),
    device=hub.Device("Samsung Galaxy S24 (Family)"),
    inputs=None,
    profile=True,
)
assert isinstance(job, hub.InferenceJob)
The return value is an instance of InferenceJob. To view a
list of all your jobs, go to /jobs/.
Running inference on a PyTorch model
This example requires PyTorch, which can be installed as follows.
pip3 install "qai-hub[torch]"
In this example, we optimize and run inference with profiling enabled on a PyTorch model using Qualcomm® AI Hub Workbench.
import torch

import qai_hub as hub

client = hub.Client()


class SimpleNet(torch.nn.Module):
    def __init__(self):
        super().__init__()
        self.linear = torch.nn.Linear(5, 2)

    def forward(self, x):
        return self.linear(x)


input_shapes: list[tuple[int, ...]] = [(3, 5)]
torch_model = SimpleNet()

# Trace the model using random inputs
torch_inputs = tuple(torch.randn(shape) for shape in input_shapes)
with torch.no_grad():
    pt2_model = torch.export.export(torch_model, torch_inputs)

# Submit compile job
compile_job = client.submit_compile_job(
    model=pt2_model,
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    input_specs=dict(x=input_shapes[0]),
)
assert isinstance(compile_job, hub.CompileJob)

# Run a job with profiling using results from the compile job
job = client.submit_inference_job(
    model=compile_job.get_target_model(),
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    inputs=None,
    profile=True,
)
assert isinstance(job, hub.InferenceJob)
For more information on options when uploading, compiling, and submitting a job, see
upload_model(), submit_compile_job(), and
submit_inference_job().
Running inference on a TorchScript model
If you already have a saved exported torch model (saved with
torch.export.save), you can submit it directly. We will use
mobilenet_v2.pt2
as an example. Similar to the previous example, you can only run inference on a
TorchScript model after it is compiled to a suitable target.
import qai_hub as hub

client = hub.Client()

# Compile previously saved torchscript model
compile_job = client.submit_compile_job(
    model="mobilenet_v2.pt",
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    input_specs=dict(image=(1, 3, 224, 224)),
)
assert isinstance(compile_job, hub.CompileJob)

job = client.submit_inference_job(
    model=compile_job.get_target_model(),
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    inputs=None,
    profile=True,
)
assert isinstance(job, hub.InferenceJob)
Running Inference with a TensorFlow Lite model
This example uses a TensorFlow Lite model SqueezeNet10.tflite to run inference.
import numpy as np

import qai_hub as hub

client = hub.Client()

sample = np.random.random((1, 224, 224, 3)).astype(np.float32)

inference_job = client.submit_inference_job(
    model="SqueezeNet10.tflite",
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    inputs=dict(x=[sample]),
    profile=False,
)

assert isinstance(inference_job, hub.InferenceJob)
inference_job.download_output_data()
The inputs for inference must be a dictionary, where the keys are the names of the features and the values are the tensors. The tensors can be a list of numpy arrays or a single numpy array if it is a single data point.
Profiling is disabled in this example.
inference_jobis an instance ofInferenceJob.
Multiple inference jobs can be launched at the same time by providing a list of
Device objects to the
submit_inference_job() API.
Running Inference with QNN DLC and Context Binaries
This example compiles a TorchScript model (mobilenet_v2.pt) to QNN DLC or QNN context binary format. Then inference is run on device with the compiled target model.
import numpy as np

import qai_hub as hub

client = hub.Client()

sample = np.random.random((1, 3, 224, 224)).astype(np.float32)

compile_job = client.submit_compile_job(
    model="mobilenet_v2.pt",
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    options="--target_runtime qnn_dlc",
    input_specs=dict(image=(1, 3, 224, 224)),
)
assert isinstance(compile_job, hub.CompileJob)

inference_job = client.submit_inference_job(
    model=compile_job.get_target_model(),
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    inputs=dict(image=[sample]),
)
assert isinstance(inference_job, hub.InferenceJob)
import numpy as np

import qai_hub as hub

client = hub.Client()

input_shape = (1, 3, 224, 224)
sample = np.random.random(input_shape).astype(np.float32)

_, link_job = client.submit_compile_and_link_jobs(
    models="mobilenet_v2.pt",
    device=hub.Device("Samsung Galaxy S24 (Family)"),
    input_specs=dict(image=input_shape),
)
assert isinstance(link_job, hub.LinkJob)

inference_job = client.submit_inference_job(
    model=link_job.get_target_model(),
    device=hub.Device("Samsung Galaxy S24 (Family)"),
    inputs=dict(image=[sample]),
)
assert isinstance(inference_job, hub.InferenceJob)
Running inference on an ONNX model
Qualcomm® AI Hub Workbench also supports ONNX models. ONNX models can be run by either compiling them to a target such as TensorFlow Lite, or run directly using the ONNX Runtime. We will use mobilenet_v2.onnx as an example of both methods. This example compiles to a TensorFlow Lite target model.
import qai_hub as hub

client = hub.Client()

compile_job = client.submit_compile_job(
    model="mobilenet_v2.onnx",
    device=hub.Device("Samsung Galaxy S23 (Family)"),
)
assert isinstance(compile_job, hub.CompileJob)

job = client.submit_inference_job(
    model=compile_job.get_target_model(),
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    inputs=None,
    profile=True,
)
assert isinstance(job, hub.InferenceJob)
This example runs inference with profiling on the ONNX model directly using the ONNX Runtime.
import qai_hub as hub

client = hub.Client()

job = client.submit_inference_job(
    model="mobilenet_v2.onnx",
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    inputs=None,
    profile=True,
)
assert isinstance(job, hub.InferenceJob)
The precompiled QNN ONNX models with a QNN context binary can also be run directly. In this example we continue the compilation example in Compiling to a Precompiled QNN ONNX and run inference with profiling on the model:
import qai_hub as hub

# Run inference with profiling on the previously compiled model
job = hub.submit_inference_job(
    model=compile_job.get_target_model(),
    device=hub.Device("Samsung Galaxy S25 (Family)"),
    inputs=None,
    profile=True,
)
assert isinstance(job, hub.InferenceJob)
Running inference an ONNX model on a device that does not support floating point
Some devices have HTPs that do not support floating point (FP32 or FP16) models. When running on those devices using the ONNX Runtime,
Qualcomm® AI Hub Workbench will not automatically enable the QNN Execution Provider. This behavior allows all models to succeed
by running them on the CPU. If you have a fully quantized model, better performance may be achieved on the NPU
by enabling the QNN Execution Provider with the option: --onnx_execution_providers=qnn.
In this example, we run a fully quantized model on the CPU using default options, and then run the model on the NPU by enabling the QNN Execution Provider.
We will use resnet50_w8a8.onnx
as an example of both methods.:
import qai_hub as hub

client = hub.Client()

# Profile a quantized model with default options - the model will run on the CPU
job = client.submit_inference_job(
    "resnet50_w8a8.onnx",
    device=hub.Device("Dragonwing RB3 Gen 2 Vision Kit"),
    inputs=None,
    profile=True,
)

assert isinstance(job, hub.InferenceJob)

# Profile a quantized model with the QNN Execution Provider
job = client.submit_inference_job(
    "resnet50_w8a8.onnx",
    device=hub.Device("Dragonwing RB3 Gen 2 Vision Kit"),
    inputs=None,
    profile=True,
    options="--onnx_execution_providers=qnn",
)

assert isinstance(job, hub.InferenceJob)
Running inference on multiple devices
Often it is important to model performance on multiple devices. In this example, we run inference with profiling on a recent Snapdragon® 8 Gen 1 and Snapdragon® 8 Gen 2 devices for good test coverage. We reuse the SqueezeNet model from the TensorFlow Lite example, but this time we run inference with proiling on two devices.
import qai_hub as hub

client = hub.Client()

devices = [
    hub.Device("Samsung Galaxy S23 (Family)"),  # Snapdragon 8 Gen 2
    hub.Device("Samsung Galaxy S24 (Family)"),  # Snapdragon 8 Gen 3
]

jobs = client.submit_inference_job(
    model="SqueezeNet10.tflite", device=devices, inputs=None, profile=True
)
A separate inference job is created for each device.
Verify model accuracy on-device using an inference job
This example demonstrates how to validate the numerics of a QNN DLC model on-device.
Reusing the model from the torchscript example (mobilenet_v2.pt)
import torch

import qai_hub as hub

client = hub.Client()

device_s23 = hub.Device(name="Samsung Galaxy S23 (Family)")
compile_job = client.submit_compile_job(
    model="mobilenet_v2.pt2",
    device=device_s23,
    input_specs={"x": (1, 3, 224, 224)},
    options="--target_runtime qnn_dlc",
)

assert isinstance(compile_job, hub.CompileJob)
on_device_model = compile_job.get_target_model()
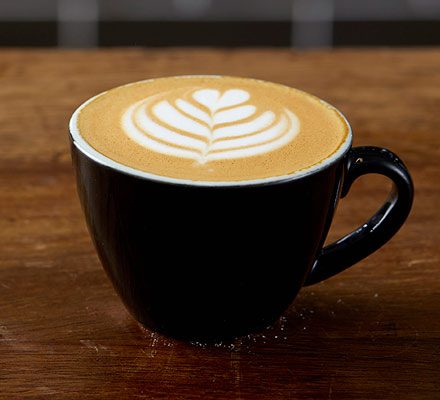
We can use this optimized .so model and run inference on it with
input data on a specific device. The input image used in this example can be
downloaded - input_image1.jpg.
import numpy as np
from PIL import Image

# Convert the image to numpy array of shape [1, 3, 224, 224]
image = Image.open("input_image1.jpg").resize((224, 224))
img_array = np.array(image, dtype=np.float32)

# Ensure correct layout (NCHW) and re-scale
input_array = np.expand_dims(np.transpose(img_array / 255.0, (2, 0, 1)), axis=0)

# Run inference using the on-device model on the input image
inference_job = client.submit_inference_job(
    model=on_device_model,
    device=device_s23,
    inputs=dict(x=[input_array]),
    profile=False,
)
assert isinstance(inference_job, hub.InferenceJob)
We can use this on-device raw output to generate class predictions and compare it to the reference implementation. You’ll need imagenet classes for this - imagenet_classes.txt.
# Get the on-device output
on_device_output: dict[str, list[np.ndarray]] = inference_job.download_output_data()  # type: ignore

# Load the torch model and perform inference
torch_model = torch.export.load("mobilenet_v2.pt2")

# Calculate probabilities for torch model
torch_input = torch.from_numpy(input_array)
torch_output = torch_model.module()(torch_input)
torch_probabilities = torch.nn.functional.softmax(torch_output[0], dim=0)

# Calculate probabilities for the on-device output
output_name = list(on_device_output.keys())[0]
out = on_device_output[output_name][0]
on_device_probabilities = np.exp(out) / np.sum(np.exp(out), axis=1)

# Read the class labels for imagenet
with open("imagenet_classes.txt") as f:
    categories = [s.strip() for s in f.readlines()]

# Print top five predictions for the on-device model
print("Top-5 On-Device predictions:")
top5_classes = np.argsort(on_device_probabilities[0], axis=0)[-5:]
for c in reversed(top5_classes):
    print(f"{c} {categories[c]:20s} {on_device_probabilities[0][c]:>6.1%}")

# Print top five prediction for torch model
print("Top-5 PyTorch predictions:")
top5_prob, top5_catid = torch.topk(torch_probabilities, 5)
for i in range(top5_prob.size(0)):
    print(
        f"{top5_catid[i]:4d} {categories[top5_catid[i]]:20s} {top5_prob[i].item():>6.1%}"
    )
The code above produces results that look like this:
Top-5 On-Device predictions:
968 cup                   71.3%
504 coffee mug            16.4%
967 espresso               7.8%
809 soup bowl              1.3%
659 mixing bowl            1.2%

Top-5 PyTorch predictions:
968 cup                   71.4%
504 coffee mug            16.1%
967 espresso               8.0%
809 soup bowl              1.4%
659 mixing bowl            1.2%
The on-device results are nearly equivalent to the reference implementation. This tells us the model did not suffer from a correctness regression and gives us confidence it will behave as expected once deployed.
To strengthen this confidence, consider expanding this to several images and using quantitative summaries, such as measuring KL divergence or comparing accuracy (if the labels are known). This also makes it easier to validate across your target devices.
Running inference using a previously uploaded dataset and model
Analogous to models, Qualcomm® AI Hub Workbench exposes an API to enable users to upload data that can be reused.
import numpy as np

import qai_hub as hub

client = hub.Client()

data = dict(
    x=[
        np.random.random((1, 224, 224, 3)).astype(np.float32),
        np.random.random((1, 224, 224, 3)).astype(np.float32),
    ]
)
hub_dataset = client.upload_dataset(data)
You can now run an inference job using the uploaded dataset. This example uses SqueezeNet10.tflite.
# Submit job
job = client.submit_inference_job(
    model="SqueezeNet10.tflite",
    device=hub.Device("Samsung Galaxy S23 (Family)"),
    inputs=hub_dataset,
)
Uploading a model for inference
It is possible to upload a model (e.g. SqueezeNet10.tflite) without submitting an inference job.
import qai_hub as hub

client = hub.Client()
hub_model = client.upload_model("SqueezeNet10.tflite")
print(hub_model)
You can now run an inference job using the uploaded model’s model_id.
In this example, we enable profiling.
import qai_hub as hub

client = hub.Client()

# Retrieve model using ID
hub_model = client.get_model("mabc123")

# Submit job
job = client.submit_inference_job(
            model=hub_model,
            device=hub.Device("Samsung Galaxy S23 (Family)"),
            inputs=None,
            profile=True,
)
Running inference on a previously uploaded model
We can reuse a model from a previous job to launch a new inference job (e.g., on a different device). This avoids uploading the same model multiple times.
import qai_hub as hub

client = hub.Client()

# Get the model from the previous job
job = client.get_job("jabc123")
hub_model = job.model

# Run inference with profiling on the model from the job
new_job = client.submit_inference_job(
    model=hub_model,
    device=hub.Device("Samsung Galaxy S22 Ultra 5G"),
    inputs=None,
    profile=True,
)